
Any store's public products
Open the store's address with /products.json?limit=250 at the end, then &page=2, &page=3 and so on. Each page is JSON already: save it with Ctrl+S (Cmd+S on a Mac). It is read-only and holds published products only.
Almost every Shopify store publishes its products as a public JSON feed. This guide explains what is in it, what is not, how to page through it, and how to save a store's products as one JSON file or an Excel sheet, by hand or without writing any code.
Add to Chrome, it's free No account · private by default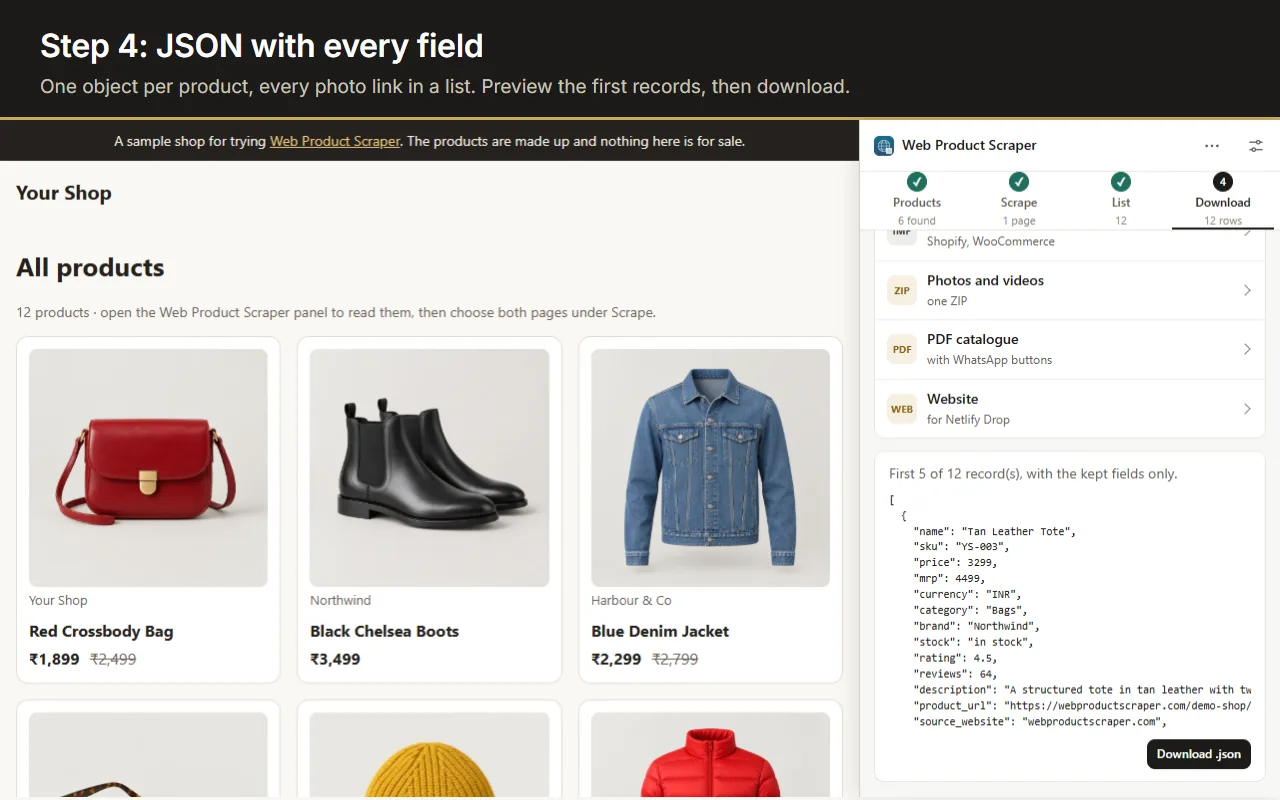
It is a public, read-only JSON feed that Shopify serves for an online store. Add /products.json to the store address, or /collections/NAME/products.json for one collection, and you get the published products as structured data: title, handle, vendor, product type, description, tags, variants with prices and SKUs, and full-size image links.
The feed answers with one object that holds a list of products. The example is shortened to one made-up product with one variant and one image, and to the keys that matter for an export; real entries also carry dates, IDs and weights.
This asks for the second page of the whole store, 250 products a page. For one collection, put /collections/NAME before /products.json.
https://shop-name.com/products.json?limit=250&page=2Prices are text in the store's currency, with no currency code. compare_at_price is the struck-out price, or null when there is none.
{
  "products": [
    {
      "id": 1000000000001,
      "title": "Red Crossbody Bag",
      "handle": "red-crossbody-bag",
      "body_html": "<p>A small crossbody bag in red leather.</p>",
      "vendor": "Your Shop",
      "product_type": "Bags",
      "tags": ["leather", "new"],
      "variants": [
        {
          "id": 2000000000001,
          "title": "Default Title",
          "sku": "YS-007",
          "available": true,
          "price": "1899.00",
          "compare_at_price": "2499.00"
        }
      ],
      "images": [
        {
          "src": "https://cdn.shopify.com/s/files/1/0000/0001/files/red-crossbody-bag-1.jpg",
          "width": 2048,
          "height": 2048
        }
      ],
      "options": [{ "name": "Title", "position": 1, "values": ["Default Title"] }]
    }
  ]
}Which route fits depends on whose store it is and what you need from it.
Open the store's address with /products.json?limit=250 at the end, then &page=2, &page=3 and so on. Each page is JSON already: save it with Ctrl+S (Cmd+S on a Mac). It is read-only and holds published products only.
The Shopify admin exports products as CSV, not JSON. For JSON with stock levels, drafts or orders, connect through Shopify's Admin API with an app installed on your store. Since 1 January 2026 new private apps are created in Shopify's Dev Dashboard; custom apps made in the admin before then keep working.
Integration services such as Make or Coupler.io connect to your store once you approve them, then send products or orders as JSON to another app, a sheet or a web address on a timetable. Free plans are limited; frequent or large syncs need a paid plan.
A bulk operation in Shopify's GraphQL Admin API exports your own store's products, with the variants and images you ask for, as one JSONL file: one JSON object per line, no paging. Shopify calls its older REST Admin API legacy, so new code should use GraphQL.
Open a collection with Web Product Scraper and download JSON in step 4: the collection's products, up to 1,000, in one file with every image link, read from the same feed.
Web Product Scraper's Webhook setting (Settings, Connections) sends every product it scrapes as JSON to a web address you enter, such as a Zapier, Make or n8n webhook. It stays off until you add an address.
| Route | Whose store | Code | What you get |
|---|---|---|---|
| The feed, by hand | Any store | No | One JSON page of up to 250 published products at a time |
| Web Product Scraper | Any store | No | One JSON, Excel or CSV file, up to 1,000 products per collection, and the photos as a ZIP |
| Its Webhook | Any store | No | Each product sent as JSON to a web address you choose |
| A short script | Any store | Yes | Every page of the feed in one file |
| Make or Coupler.io | Your own | No | Products or orders as JSON on a schedule; free plans are limited |
| Admin API | Your own | Yes | Everything, with stock, drafts and orders; a bulk export gives one JSONL file |
The same fields for every product, whatever the theme.
The product name, and the handle: the last part of the product address, as in /products/HANDLE.
The brand or supplier name the shop entered, and the product type it uses to group products.
The full description as HTML, with the formatting tags the shop used.
One entry per size, colour or option: price, compare-at price, SKU, the option values, and whether it is available.
Links to every product image at its original size, in the shop's order.
The product tags, and when it was created, published and last updated.
No stock counts. A variant says whether it is available, not how many are left.
No currency. Prices are plain numbers in the store's currency; the currency is shown on the store's pages, not in the feed.
Only published products. Drafts, archived products and password-protected stores are not in it.
No reviews or extra fields from apps. Reviews, size charts and custom fields usually come from apps and are not part of the feed.
Some stores do not serve it at all: a store built on a custom (headless) storefront may answer with an error instead.
This is what Web Product Scraper does on a Shopify collection page.
Open a collection page of the store, an address ending in /collections/NAME, and click the extension icon.
It fetches /collections/NAME/products.json 250 products at a time, up to 1,000 products per collection. It reads the feed only on a collection page: on a tag page (/collections/NAME/TAG), a search, or a store with no feed, it reads the product cards on the page instead.
One row per product unless you tick Variants: the lowest variant price, the highest compare-at price above it as the MRP, the first SKU found, the vendor as brand and the product type as category. The currency comes from the page.
JSON (one object per product, with every image link in a list), Excel or CSV, or a ZIP with every image in a folder per product, named after it.
Web Product Scraper reads these fields from each product entry. Tick Variants for one row, or JSON object, per size or colour, each with its own price, SKU and stock.
| products.json field | Column in Excel, CSV and JSON | How it is read |
|---|---|---|
| title | name | As it is. |
| variants: price | price | The lowest price of all variants, as a number. |
| variants: compare_at_price | mrp | The highest compare-at price, only when it is above the price. |
| variants: sku | sku | The first SKU found among the variants. |
| variants: available | stock | in stock when any variant is available, otherwise out of stock. |
| vendor | brand | As it is. |
| product_type | category | As it is. |
| body_html | description | The HTML turned into plain text. |
| images: src | image_1 to image_12 | Full-size links, up to twelve in Excel and CSV; JSON keeps them all in one list called images. |
| id | external_id | The product's Shopify ID. |
| not in the feed | currency | Read from the store's page. |
| tags, dates, options, IDs, grams | none | Not exported. |
A real JSON file saved by the extension from its sample shop: 12 made-up products, both pages, read in Full. The sample shop is not a Shopify store, but the keys are the same on any shop; a key is left out when no product has a value for it.
If you write code, a short script does the same as paging by hand.
It asks for one page at a time with limit=250 until a page holds fewer than 250 products, pauses two seconds between requests, and saves every product in one file. Many stores refuse scripts with error 429 (too many requests) even when the same address opens in a browser. The work is then in the details: which variant's price to show, turning the description HTML into text, and downloading the images. The extension does those for you and needs no setup.
import json, time, urllib.request

store = "https://shop-name.com"   # the store's address
products, page = [], 1
while True:
    url = f"{store}/products.json?limit=250&page={page}"
    with urllib.request.urlopen(url) as response:
        batch = json.load(response)["products"]
    products += batch
    if len(batch) < 250:
        break
    page += 1
    time.sleep(2)   # a pause between requests

with open("products.json", "w", encoding="utf-8") as f:
    json.dump(products, f, indent=2, ensure_ascii=False)
print(len(products), "products saved")There is no simple setting in the Shopify admin to switch it off, which is why the question comes up on Shopify's own community forum. The feed shows only what the store already shows to every visitor: published products, their prices and their photos.
Using it is still your responsibility. Read the store's terms, take only what you need, and keep a pause between requests.
For a store's public products, no connection is needed: its address plus /products.json returns them as JSON, 250 per page. For orders, stock or unpublished products you need the store owner's access through Shopify's Admin API. To turn the public feed into a spreadsheet instead, Web Product Scraper reads it from any collection page.
No. The Admin API needs the store owner's permission and returns everything, including stock and unpublished products. products.json is the public storefront feed: read-only, published products only.
The feed is paged. Add ?limit=250 for the largest page and &page=2, &page=3 for the rest.
Yes: /collections/NAME/products.json, where NAME is the last part of the collection's address.
No. It uses the feed when a Shopify collection has one, and reads the product cards on the page otherwise, so it also works on other platforms.
products.json already lists only published products, the ones visitors can see. In your own admin, filter the Products list to Active status (and the Online Store sales channel if you also sell elsewhere), then choose Export and "products matching your search".